Cloud agents need strict context controls today
Google Cloud customers now process over a massive volume of tokens per minute. That scale has blown past traditional security perimeters.
The math is simple: without rigorous governance frameworks and zero-trust architecture, rapid deployment of autonomous agents invites catastrophic data leakage. As organizations rush to integrate digital twins and fractional GPUs, the attack surface expands faster than IT teams can audit. We need to dissect the critical vulnerabilities inherent in modern cloud AI tools and outline a path to secure operations.
Here is the reality check. The Model Context Protocol changes API boundaries, making JSON-RPC tool authorization non-negotiable for preventing prompt injection. We must examine the mechanics of Extended Agent Gateway patterns to isolate workloads and demonstrate how BigQuery Graph supply chain mapping identifies hidden dependencies before they become breaches. Finally, we detail methods to achieve measurable ROI through strict token quota management and optimized LLM access controls. Only verified API management strategies will survive the next quarter's threat environment.
The Role of Model Context Protocol and Digital Twins in Modernizing Enterprise Data
Model Context Protocol and BigQuery Graph Digital Twins Set
Model Context Protocol gives artificial intelligence agents a uniform way to locate and call external tools. This specification kills the need for custom integrations by defining a shared vocabulary for tool descriptions. AI systems can now engage with varied data sources without proprietary adapters. Companies adopting this standard sidestep vendor lock-in while accelerating the rollout of agentic workflows across hybrid infrastructures.
Guru Rangavittal and Candice Chen demonstrated how BigQuery Graph lets organizations construct digital twins by converting physical assets into linked nodes. Their method maps supply chain components to graph structures, facilitating complex relationship queries that traditional tables handle poorly. The resulting topology enables enterprises to simulate cascading failures or refine logistics routes using native graph traversals.
Widespread adoption forces a shift from experimental prototypes to governed production systems. The agentic maturity ladder outlines this evolution from basic chatbots to autonomous agents executing multi-step business processes with verified outcomes. Nearly a majority of Google Cloud customers are using AI products to power their businesses as of mid-2026. Combining these graph-based twins with S3-compatible object storage manages unstructured media assets often tied to graph nodes. Storing large binary objects in cost-optimized buckets while keeping metadata pointers in the graph prevents performance degradation as twin fidelity grows. This architecture meets the high-throughput needs of AI training pipelines without complicating the underlying data model.
Real-World Impact: Query Time Reduction and Architecture
Agentic maturity tracks an enterprise move from isolated prototypes to governed production systems managing critical data paths. Look at Suzano, the world's largest pulp manufacturer. They achieved a significant reduction in query time for 50,000 employees by using an AI agent with Gemini Pro to translate natural language into SQL.
Deployments converting natural language to SQL for large workforces show a shift away from monolithic AI models toward micro-agent architecture. Monolithic systems run every request through one large model. Micro-agents route specific tasks to optimized instances, cutting latency and token use. Google Cloud customers process more than a vast number of tokens per minute via direct API use as of 2026.
Governance Risks in Centralizing MCP Servers and LLMs
Centralizing Model Context Protocol servers builds a single point of failure for enterprise tool access. Traditional APIs enforce rigid schemas, but MCP dynamically exposes tools to AI agents. This widens the attack surface if JSON-RPC tool authorization lacks strict validation.
This architectural change requires moving from monolithic AI designs to a micro-agent architecture where distinct agents hold minimal necessary permissions. Technical deep dives on AI gateways address centralizing governance over MCP servers and protecting LLMs through such interfaces. Unauthorized data exfiltration occurs when agents inherit broad context without granular scope limits. Operators must implement quota management to stop runaway token consumption that could exhaust budgets or degrade service. Centralized control planes become high-value targets for credential theft without structured oversight. Increased configuration complexity is the cost of isolated failure domains. Organizations must define clear boundaries for agent actions to close these governance gaps effectively. S3-compatible storage provides the foundation these systems need for secure, high-performance data access.
Inside the Extended Agent Gateway and Zero-Trust Security Architecture
Extended Agent Gateway as the Secure MCP Entry Point
The Extended Agent Gateway intercepts every Model Context Protocol request before backend systems ever see the traffic. This component converts standard REST APIs into governed MCP servers by validating identity and context at the network edge instead of burying logic inside applications. Operators wrap legacy endpoints with policy checks that enforce tenant isolation and tool authorization boundaries.
| Feature | Traditional API Gateway | Extended Agent Gateway |
|---|---|---|
| Protocol Focus | HTTP/REST | JSON-RPC over MCP |
| Authorization | Token-based access | Fine-grained tool scope |
| Context Handling | Stateless headers | Session-aware memory |
| Primary Risk | Over-permissive keys | Unbounded agent actions |
Mapping existing cloud regions to specific security zones requires data from tools like Cloud Location Finder to satisfy data sovereignty rules. The gateway extracts tenant context from incoming traffic and invokes the corresponding agent runtime only after successful policy verification. Transforming unstructured REST payloads into typed MCP arguments introduces latency penalties that real-time inference workloads must absorb.
Strict JSON-RPC validation conflicts with the low-latency responses interactive digital twin simulations demand. Tuning timeout thresholds and caching strategies at the gateway level helps balance these competing needs.
Enforcing Fine-Grained Authorization on Transformed REST-to-MCP Flows
Converting a REST endpoint into a secure MCP server demands wrapping every JSON-RPC call with real-time Fine-Grained Authorization checks. This shift stops AI agents from executing unauthorized actions by validating user intent against explicit resource permissions before the request reaches backend logic. Inserting an interception layer parses tool definitions and enforces scope limits dynamically.
- Parse incoming JSON-RPC requests to identify the specific tool and target resource.
- Query the policy engine to verify the caller's identity against the requested action.
- Block or allow the flow based on real-time context rather than static tokens.
Traditional gateways rely on broad token access, whereas this approach isolates risk at the function level. Latency-sensitive applications may suffer added milliseconds when complex policy evaluations occur. Skipping this step creates measurable exposure: autonomous agents might inadvertently reveal sensitive data paths. Rigorous testing balances security depth with performance requirements.
| Capability | Standard REST Security | MCP-Transformed Security |
|---|---|---|
| Scope | Endpoint-level | Tool-level |
| Context | Static headers | Flexible intent |
| Enforcement | Pre-routing | Real-time evaluation |
An AI Command and Control webinar highlights the necessity of governed endpoints for enterprise adoption. Rabata.io enables organizations to implement these secure patterns using S3-compatible storage that scales with AI training data needs. Increased configuration complexity yields a drastically reduced risk surface. Enterprises must prioritize this architectural shift to safely deploy production AI systems.
Zero-Trust Validation Checklist for AI Agent API Calls
Verify tenant identity assertions before allowing any Model Context Protocol request to reach backend logic. This mandatory gate prevents lateral movement by ensuring every JSON-RPC call carries explicit scope definitions rather than relying on static network boundaries. Engineers must validate that the calling agent possesses the exact tool permissions required for the specific action, rejecting broad administrative tokens in favor of ephemeral, task-limited credentials.
The Extended Agent Gateway enforces these rules by parsing request headers against a flexible policy engine. Traditional APIs trust the network perimeter, but this architecture treats every packet as untrusted until cryptographic proof of context appears.
| Validation Layer | Legacy REST Approach | Zero-Trust MCP Standard |
|---|---|---|
| Identity Scope | Service Account Wide | Per-Tool Ephemeral |
| Context Check | Static Header Match | Flexible Graph Traversal |
| Failure Mode | Silent Drop | Explicit Deny Log |
Rabata.io recommends deploying strict Fine-Grained Authorization checks that interrogate the digital twin state before authorizing data access. Neglecting the memory state of an agent creates a common oversight. Without validating conversation history against current permissions, an attacker could replay old commands to bypass fresh restrictions.
- Extract the caller's identity and requested tool name from the JSON-RPC payload.
- Cross-reference the identity against the BigQuery Graph to verify current relationship validity.
- Confirm the requested action falls within the least-privilege boundary for that specific context window.
- Log the decision with full context attestation before forwarding the packet.
Developers can test these validation flows using the Android devices available in the Google AI Edge Portal to simulate diverse client environments. New capabilities to benchmark and debug LLM performance are available in private preview, offering deeper visibility into latency spikes caused by excessive authorization checks. Increased initial configuration complexity results in a resilient system where unauthorized API calls fail at the edge.
Measurable ROI from Fractional GPUs and Graph-Based Supply Chain Optimization
Fractional GPU Economics and Resource-Based CUD Sharing Mechanics
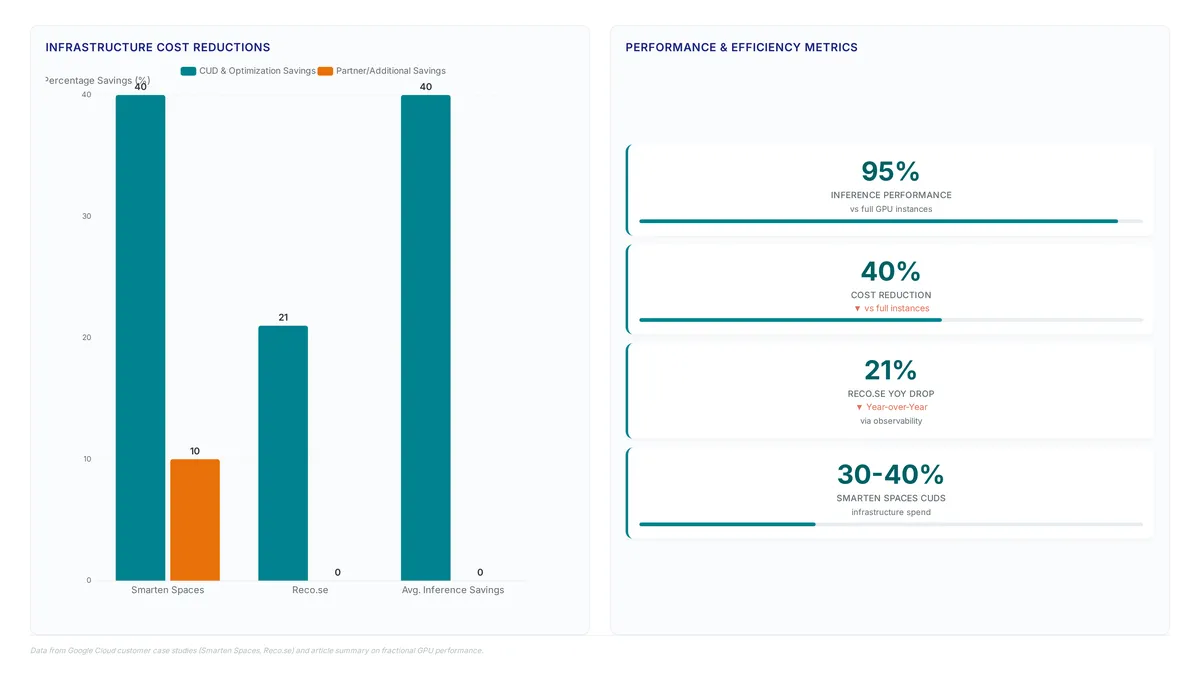
Fractional GPU workloads apply accelerator memory to support granular cost attribution for AI workloads. Google Cloud has expanded its AI Hypercomputer architecture with higher-performance file services, quicker shared storage, and new metadata intelligence capabilities, positioning storage as an active contributor to AI workload performance rather than a background repository. These updates provide a thorough storage portfolio, offering raw power alongside optimal storage services for each use-case to help innovate quicker and optimize for cost efficiency.
Intermittent inference or batch training jobs see the most dramatic economic shifts from these changes. The update aims to maximize savings by pooling underutilized discounts, though users retain control to adjust preferences via CUD scope configuration. Centralized savings can obscure individual project costs if chargeback models rely on raw consumption data. Operators must implement strong tagging strategies to track usage accurately within the shared pool.
Production AI environments frequently ask GPU memory to handle both computation and context storage simultaneously. Performance bottlenecks emerge when GPUs are forced to do both. Purpose-built storage should coordinate with GPU memory to hold large volumes of reusable context across active inference sessions. This approach delivers predictable performance for high fan-out access patterns common in modern AI training.
Applying BigQuery Graph Digital Twins to Supply Chain Node Optimization
This architectural shift allows logistics teams to model complex dependencies that traditional relational tables often obscure. By mapping warehouses, transit routes, and inventory batches as graph elements, operators gain the ability to trace disruption paths instantly.
The mechanism relies on defining vertex types for locations and edge types for movement capabilities.
| Component | Function | Optimization Target |
|---|---|---|
| Vertex Types | Define static assets within the supply chain | Node density reduction |
| Edge Types | Represent valid transit links or supply flows | Pathfinding latency |
| Properties | Store flexible metrics like current capacity | Real-time filtering |
Adopt this micro-agent architecture when query patterns shift from simple lookups to multi-hop relationship traversals. A single agent can manage inventory state while another monitors route viability, communicating through the shared graph context. Maintaining graph schema consistency across distributed teams presents a tangible operational overhead.
Specialized storage provides the foundation required to persist the massive event logs fueling these digital twins. Storing immutable historical snapshots on cost-effective storage ensures that graph reconstruction for audit or retraining remains economically viable. Cloud-native graph engines provide the query interface. The underlying data lake must scale without linear cost increases. The limitation lies not in query speed but in the initial data modeling effort required to abstract physical reality into node-edge pairs. Enterprises ignoring this modeling debt risk building fragile twins that fail under production load. Strategic adoption requires balancing graph fidelity against maintenance burden.
Centralized MCP Governance Versus Distributed LLM Protection Strategies
Centralizing Model Context Protocol governance simplifies policy enforcement but introduces a single latency bottleneck for high-volume token processing. Operators must choose between a unified control plane and localized LLM protection layers that preserve edge performance. A centralized API gateway offers consistent JSON-RPC tool authorization across the enterprise, ensuring strict compliance for sensitive data access. Routing every inference request through a central hub can degrade response times on resource-constrained edge devices. Distributed strategies mitigate this by enforcing quotas locally. Inconsistent security postures arise without rigorous synchronization.
Absolute governance consistency conflicts with the low-latency requirements of real-time AI agents. This architectural decision directly impacts cost efficiency and throughput for organizations managing fractional GPU clusters.
| Strategy | Primary Advantage | Operational Risk |
|---|---|---|
| Centralized | Unified audit logs | Single point of failure |
| Distributed | Low latency edge response | Policy drift across nodes |
Durable, S3-compatible object storage provides the foundation required for both architectures, ensuring training data remains accessible regardless of the governance model chosen. Centralized models simplify compliance. Distributed approaches often yield improved performance for latency-sensitive workloads. The optimal path depends on whether an organization prioritizes strict regulatory adherence or maximum inference speed. Deploying the wrong topology for a specific use case can negate the economic benefits of fractional GPU adoption.
Implementing EvalOps and Benchmarking LLMs on Android Devices
Google AI Edge Portal and Private Preview Benchmarking Tools
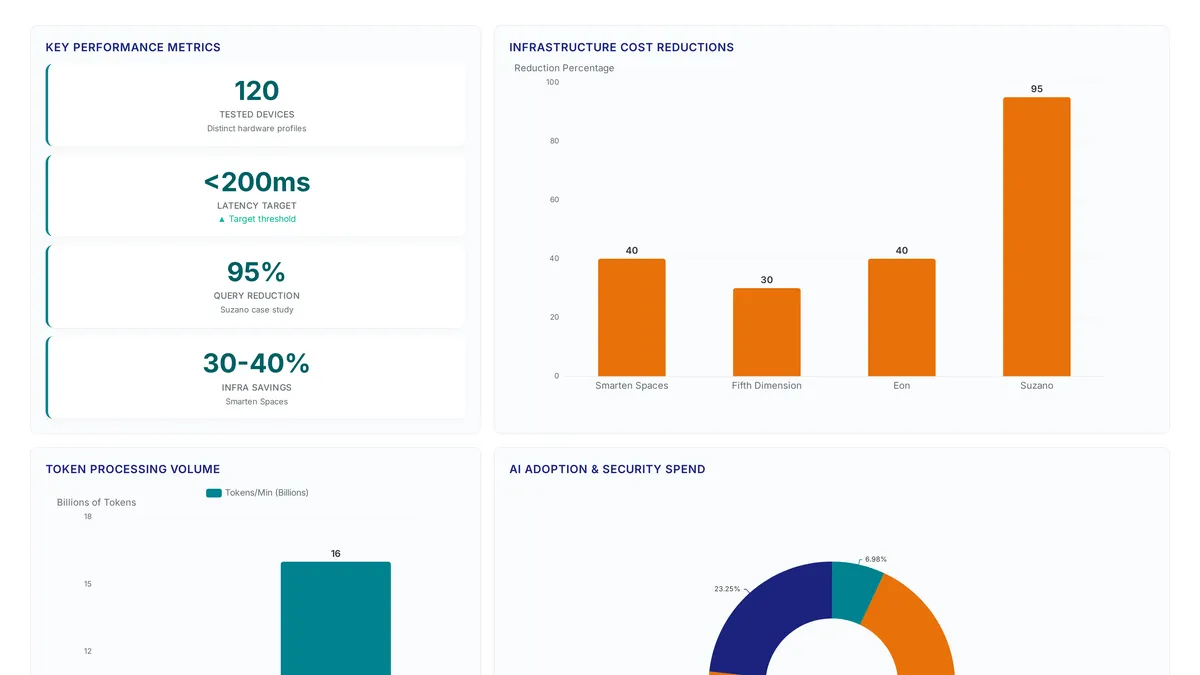
Developers access distinct hardware profiles through the Google AI Edge Portal to validate model latency before deployment. This platform allows developers to test AI performance on over 120 Android devices, supporting initial prototyping phases by providing cloud-hosted inventory for testing.
- Select a target Android form factor from the available cloud-hosted inventory.
- Upload the quantized model candidate to the debugging environment.
- Execute stress tests against the inference pipeline while monitoring thermal throttling limits.
- Capture token generation rates across varying batch sizes to identify bottlenecks.
The primary analytical insight here involves the tension between simulation fidelity and iteration speed; relying solely on emulated environments can mask hardware-specific memory fragmentation issues that only appear on physical silicon. While cloud access accelerates the initial feedback loop, final validation requires on-device testing to account for real-world OS scheduling variances. Storing these benchmark artifacts in S3-compatible object storage helps maintain an immutable audit trail for compliance reviews. This approach ensures that performance regression data remains accessible for future model iterations. The cost of ignoring these granular performance metrics is measurable in degraded user experience and increased compute waste during production scaling.
Deploying EvalOps Pipelines for Continuous Android Model Validation
Edge hardware frequently throttles inference throughput when thermal limits exceed design specifications, forcing early pipeline failure. Operators must construct automated loops that detect these regressions before they impact user experience.
- Configure the evaluation pipeline to ingest model artifacts directly from the build registry.
- Route test traffic through cloud-hosted profiles representing diverse Android form factors.
- Monitor latency percentiles continuously to capture tail latency spikes caused by background processes.
- Trigger automated rollbacks if accuracy drops below the set threshold for consecutive runs.
The Google AI Edge Portal provides access to distinct hardware profiles for validating model behavior. This approach allows teams to stress-test the inference pipeline against real-world thermal constraints effectively.
| Metric | Simulation Only | Continuous EvalOps |
|---|---|---|
| Thermal Throttling | Estimated | Measured |
| Background Noise | Absent | Present |
| Regression Detection | Manual | Automated |
A critical tension exists between maintaining high token generation rates and preserving battery life on consumer devices. Optimizing strictly for speed often ignores the power budget, leading to poor retention. The limitation of static benchmarking is its inability to predict how background applications interfere with model execution. Using S3-compatible storage scales with evaluation data volume, ensuring low-cost retention for long-term trend analysis.
Continuous validation reveals that a significant portion of performance degradation stems from memory pressure rather than compute limits. This insight shifts optimization focus from quantization to memory management strategies.
Mitigating Latency Spikes and Memory Constraints on Edge Hardware
Thermal throttling on Android devices cuts inference throughput when component temperatures exceed safe operating limits.
- Implement aggressive memory pruning strategies to reclaim RAM before the operating system kills the process.
- Schedule background inference tasks during idle thermal windows to avoid compounding heat from user interaction.
- Configure flexible batch sizing to reduce compute load immediately upon detecting temperature spikes.
Operators often overlook that persistent thermal stress degrades long-term battery health, creating a secondary failure mode beyond simple latency. Unlike cloud environments where cooling is managed centrally, edge hardware requires strict resource budgeting to maintain uptime. The limitation is that aggressive throttling protects the device but can render real-time applications unresponsive. Enterprises requiring consistent performance without local hardware variance should offload heavy workloads to scalable infrastructure for rapid retrieval and processing. This approach bypasses local thermal constraints entirely by shifting computation to scalable infrastructure. Memory exhaustion remains a hard ceiling that software tweaks cannot fully eliminate on constrained devices.
About
Marcus Chen is a Cloud Solutions Architect and Developer Advocate at Rabata.io, specializing in S3-compatible object storage and AI/ML data infrastructure. His daily work involves designing scalable storage architectures for generative AI startups, directly connecting to the critical need for securing Google Cloud agents. As organizations deploy complex AI ecosystems involving BigQuery Graph and MCP servers, the underlying data layer must remain reliable, compliant, and cost-effective. Chen's expertise in benchmarking performance and managing token quotas ensures that enterprise AI initiatives do not compromise on data governance or operational efficiency. At Rabata.io, a provider of high-performance, GDPR-compliant object storage, Chen helps teams manage the massive datasets required for LLM optimization and digital twins. By focusing on secure, S3-compatible storage foundations, he enables developers to build resilient AI agents without vendor lock-in, ensuring that the backbone of any AI strategy remains transparent and reliable.
Conclusion
Scaling AI beyond the cloud reveals that local hardware constraints, not algorithmic complexity, often dictate real-world performance limits. While edge optimization helps, relying on device-level thermal management creates unpredictable latency that static benchmarks fail to capture. The operational cost of managing these variance spikes across thousands of endpoints quickly outweighs the benefit of local processing for critical workflows. Enterprises must recognize that true reliability requires shifting heavy inference workloads to infrastructure designed for consistent throughput rather than fighting the physical limits of consumer silicon.
Organizations should commit to a hybrid architecture strategy within the next two quarters, reserving edge execution for low-latency preprocessing while offloading complex reasoning to scalable cloud environments. This approach ensures that battery life and thermal throttling do not compromise user experience or data integrity. The window for treating edge devices as primary compute nodes for heavy AI tasks is closing as models grow more demanding.
Start this week by auditing your current edge deployment logs to identify instances where thermal throttling or memory pressure caused task failures or significant delays. Use this data to justify migrating intensive workloads to a managed platform like Rabata.io, which handles scale without the physical degradation risks inherent to edge hardware.
Frequently Asked Questions
Unmanaged agents cause token sprawl that erodes performance gains.
Mature architectures drastically reduce latency by routing tasks to optimized instances.
Rapid deployment without zero-trust frameworks invites catastrophic data leakage.
Digital twins enable complex relationship queries that traditional tables handle poorly. This approach allows enterprises to simulate cascading failures effectively, supporting the shift toward governed production systems used by most major cloud customers today.
Micro-agents cut latency and token use by routing specific tasks to optimized instances.
References